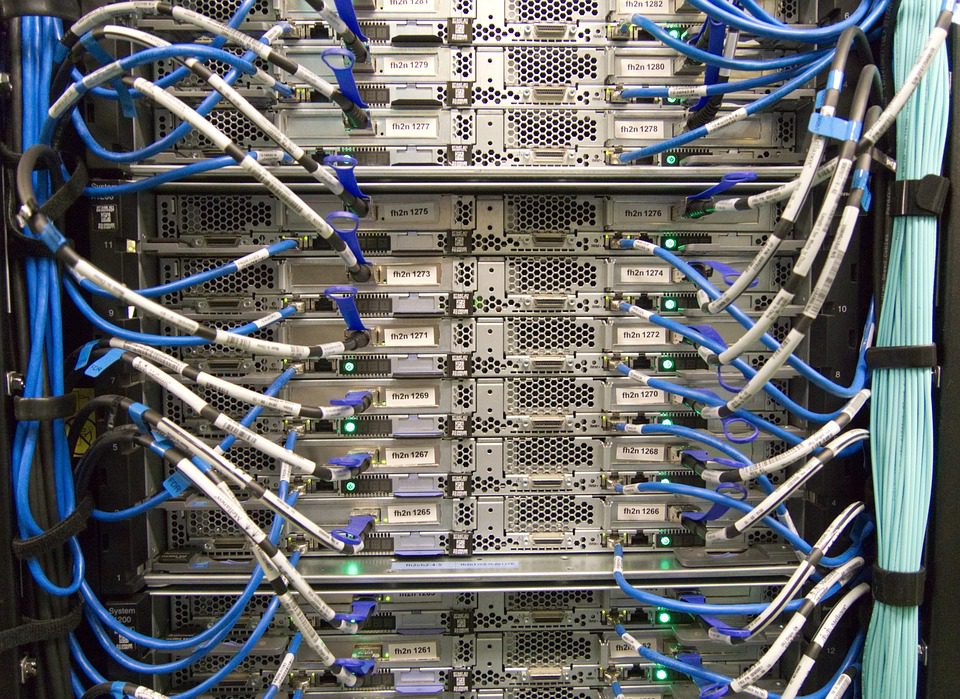
A VPS is not a permanent tier. It is a sizing decision that stays valid only while the workload’s peak fits inside the CPU shares, memory ceiling and disk queue you were given. The problem is that most teams notice the crossover a week late, after players have already churned. The five numbers below are the ones worth watching weekly. Two of them alone will tell you the decision point has passed: a steal-time average above 8% sustained for seven days, and a 1% low frame time on the game server that has grown by more than 40% against your launch baseline.
None of these metrics requires a commercial dashboard. A Granfana panel fed by node_exporter at a 5-second scrape interval, plus a per-tick timer inside the game server, is enough. Collect for two weeks before you set thresholds, so the numbers reflect your real player curve rather than a quiet test window.
Metric 1: Steal Time, Not Load Average
Load average on a virtual machine is a lie told by a scheduler you do not control. Steal time (%steal in top, node_cpu_seconds_total{mode="steal"} in Prometheus) is the fraction of wall-clock time the hypervisor gave your vCPU to someone else. On a quiet single-tenant node it sits under 1%. On a contended host with 24 vCPUs over 4 physical cores, it can swing between 0.5% and 30% across a single afternoon.
The trigger: 8% average over any rolling 7 days, or three separate 15-minute windows in a month above 20%. Below 8%, a bigger VPS plan usually fixes it. Above 20% during peak hours, you are not short of CPU — you are short of a scheduler, and buying more vCPUs on the same host family often changes nothing because the oversubscription ratio is unchanged. That is the point at which moving to dedicated hardware or a host that publishes its core-per-vCPU ratios becomes the cheaper answer.
Metric 2: 1% Low Tick Time on the Game Server
Average tick time is useless for player experience. A 64-tick Counter-Strike 2 or Source server has 15.6 ms per tick; a 128-tick server has 7.8 ms. If your average is 6 ms but the 1% worst ticks land at 34 ms, players feel stutter on every gunfight even though the dashboard looks healthy. Instrument the tick loop to record duration per tick into a circular buffer, then compute the 99th percentile once a minute.
Trigger: p99 tick time above 80% of the tick budget for more than 10 minutes in an hour. For 128-tick that means sustained p99 above 6.2 ms. Match it against steal time on the same graph. If tick p99 spikes line up with steal spikes, the host is the cause. If they line up with your own world-save or plugin activity, the fix is architectural — split the save to a replica, throttle an admin plugin — and dedicated metal will only hide the problem for a season.
Metric 3: Peak Concurrent Players vs. Per-Slot RAM
Every game engine has a measured bytes-per-player figure. Minecraft Java with default settings and no chunk pre-generation runs roughly 60-90 MB per active player on top of a 2-4 GB base. Rust servers budget 40-60 MB per connected player; ARK: Survival Evolved, notoriously heavier, can exceed 150 MB. Measure it rather than trust a forum post: record RSS at 50, 100 and 150 concurrent players and fit a line. The slope is your real per-player cost.
Trigger: peak-hour RSS above 85% of installed RAM for five consecutive days, or swap-in above 200 pages per second during a player surge. A VPS at that ceiling is being rescued by swap, and swap on a shared storage backend adds 3-15 ms of latency to any page fault — invisible in CPU graphs, very visible in tick p99. Since a 32 GB dedicated box with an NVMe pair commonly costs close to a 16 GB high-spec VPS plan, this is often the first metric that makes the upgrade arithmetic look obvious.
Metric 4: Disk Write Queue and io_wait During Saves
World saves are bursty. A 4 GB Minecraft region write or a Rust server savegame flush produces a short megabyte storm, and on a VPS the backing store is shared even if your virtual disk claims to be local SSD. Watch await per device in iostat -x 5 and %iowait in vmstat 5. Healthy NVMe stays under 2 ms await at a queue depth of 1-4.
Trigger: await above 20 ms during saves on three consecutive save cycles, or %iowait above 15% for more than 90 seconds at a time. If your host offers a local NVMe tier at a modest premium, test it before you move — many “VPS to dedicated” migrations are actually “network SSD to NVMe” migrations. If the local tier still shows 20 ms await, you have exhausted the storage product line and a dedicated chassis with two enterprise NVMe drives in a mirror is the real fix.
Metric 5: Monthly Cost per Concurrent Slot
This is the only metric that decides the move on its own. Divide total monthly spend — plan plus bandwidth overage plus backup storage plus the add-ons you forgot about — by your 95th-percentile concurrent player count. A well-priced dedicated server at $130/month carrying 400 peak players is $0.33 per slot. A VPS at $95/month that now peaks at 180 players is $0.53 per slot and falling further every month as you add resets and mods.
Trigger: when cost per concurrent slot has risen two months in a row and the plan above yours is within 30% of a dedicated quote. At that point incremental VPS upgrades stop being efficient: each tier buys you 4 GB and two shares for the same money that buys 64 GB and full cores elsewhere. Our guide to dedicated server hosting plans and hardware tiers lists current core counts and RAM per price band so you can run that comparison in one sitting.
How the Five Metrics Combine
One metric firing is noise. Two firing in the same week is a pattern. Three or more means the VPS is no longer the right shape, regardless of how much you like the panel. In practice, teams that run this scorecard weekly see the combination arrive in a predictable order: tick p99 drifts first, steal time second, RSS third. Disk await usually follows within a month, and cost per slot confirms it.
Write the thresholds into an alerting rule set so the decision is not a judgment call made at 2 a.m. after a bad raid night. A 90-day record of these five numbers also gives you a negotiating position: you can prove to a provider, or to yourself, exactly when the workload outgrew the plan. Teams planning a migration in stages should read our notes on gaming server hosting with bare-metal options for how the handover is sequenced without losing player data.
Sizing the Dedicated Box From the Same Numbers
Do not size the new server from the old plan’s specs. Size it from the metrics. Take peak concurrent players, multiply by your measured per-player RAM slope, add the base footprint, then add 25% headroom for map changes and mod packs. Take p99 tick time under load and compute the core count that would put it at 40% of budget. Use the NVMe await figure to decide whether you need two drives mirrored or can accept a single drive with backups.
As a worked example: 220 peak players at 85 MB each is 18.7 GB, plus a 4 GB base is 22.7 GB, plus 25% is 28.4 GB — a 32 GB box, not 64. For CPU, if p99 tick is 6.5 ms at 8 vCPUs on a contended host and you need 3.1 ms, 16 dedicated cores with no steal will comfortably land there. That is a smaller, cheaper machine than teams usually buy, and it is the direct product of measuring rather than guessing.
What to Do in the Week Before You Move
Freeze plugin changes, keep the old VPS running in parallel through the first weekend, and mirror world files on a 15-minute rsync cycle so a rollback is a DNS change rather than a restore. Move during your lowest-concurrency window — for most EU/US mixed communities that is Tuesday 04:00-07:00 UTC. Keep the scorecard running on the dedicated box for a month so you learn its baseline instead of assuming the problem is solved.
Related Articles:
 How to Migrate Game Servers Between Dedicated Hosting Providers Without Downtime
 Palworld Server RAM and CPU Benchmarks: Configuring for 4 to 32 Players
 Sizing a 100-Slot Game Server Network: CPU, RAM, and Bandwidth Budgets Per Instance
 Game Server Ports: Complete TCP/UDP Port Reference for Minecraft, ARK, Palworld, Rust, and More
Leave a Reply
You must be logged in to post a comment.